
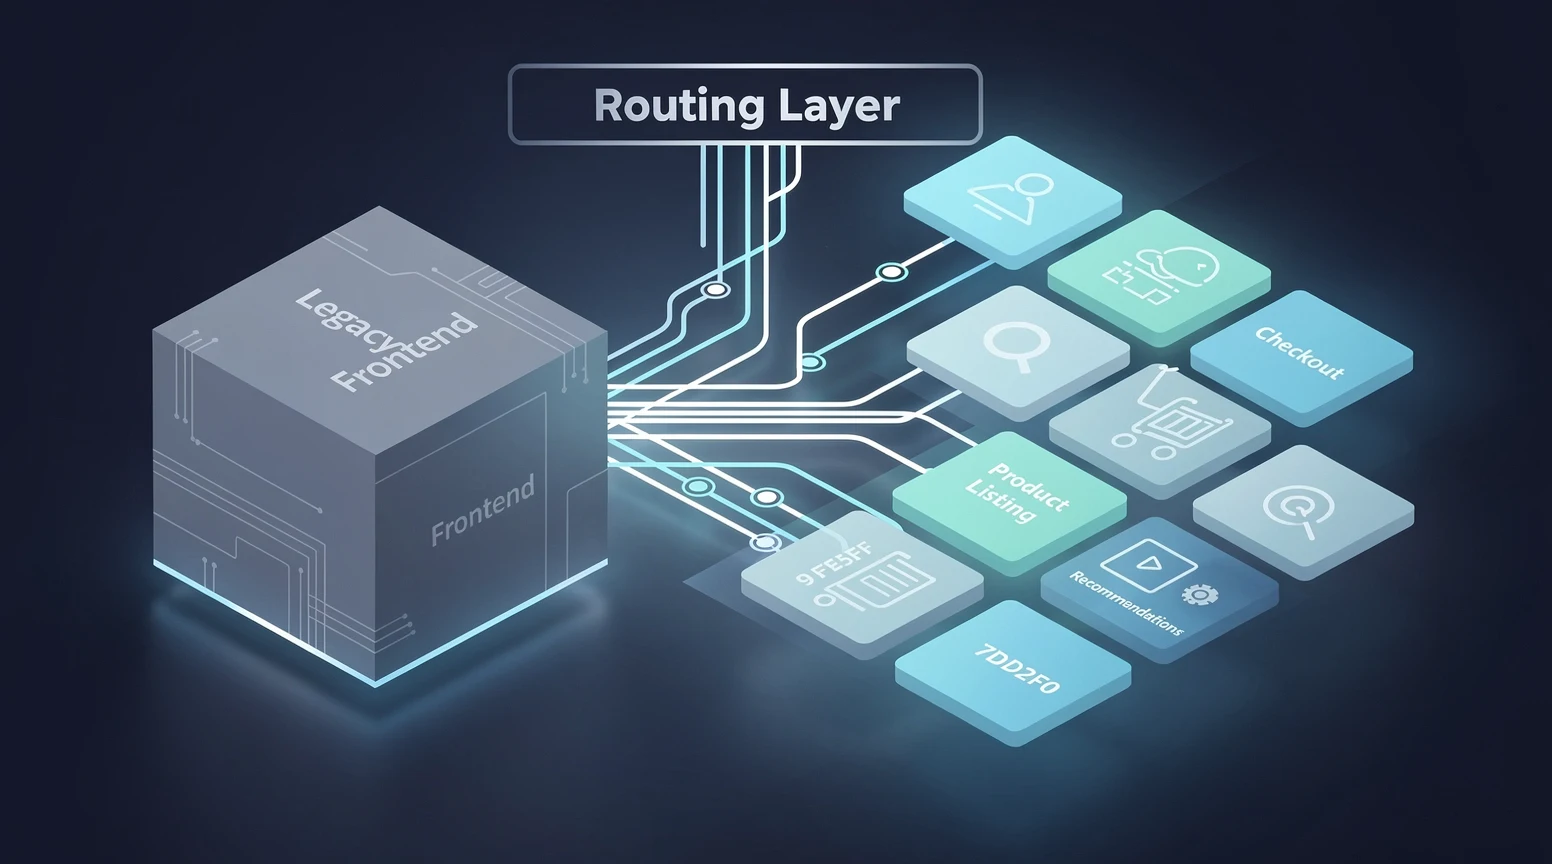
Replatforming decisions usually get framed as a choice between two architectures. The more consequential choice is how many page types you move on the same night. A storefront that cuts over its entire front end in one deploy has bet its full revenue line on a single release, and the rollback window closes the moment the first order lands in the new stack.
The phased alternative borrows a pattern from backend engineering: wrap the legacy system, move one piece of it at a time, and let the old code keep serving everything you have not migrated yet. It sits downstream of the platform decision itself, which is covered in how to choose the right e-commerce platform for your store. In commerce, that means your category pages can run on a new framework while your product detail pages still render from the monolith, with shoppers never seeing the seam. This guide walks through how retail teams sequence that work, what the routing layer has to do, and where the SEO and analytics risks actually sit.
In short
- Big bang replatforms concentrate risk into one release where every page type, every tag and every redirect has to be correct simultaneously.
- The strangler pattern puts a routing layer in front of both front ends, so traffic for migrated routes goes to the new stack and everything else falls through to the old one.
- Content and category pages are the usual first phase, because they are high in traffic, low in transactional risk and the easiest to compare against a control.
- URLs, canonicals and redirect chains are the fragile part, not the rendering layer; a route that changes shape mid-migration can cost organic traffic for months.
- Checkout moves last or never, and phase one should end with a written decision point: continue, pause, or stop with the hybrid in place permanently.
Why one big launch fails so often
The failure mode is rarely the new technology. It is the number of things that have to be simultaneously correct. A full front-end cutover asks a team to get routing, rendering, caching, redirects, structured data, consent management, tag firing, personalization rules, promotion logic and search indexing all right in the same window, on page types nobody has load tested against real holiday traffic.
Each of those is individually tractable. Combined, they produce a release where a single mistake is hard to isolate. If conversion drops 8% on launch night, the team has forty candidate causes and no way to A/B the architecture against itself. The usual response is to roll forward with patches rather than roll back, because rolling back means reverting DNS and cache layers that other teams now depend on.
There is also a planning distortion. Big bang projects produce a long pre-launch phase where nothing ships and nothing is measurable, which is precisely when sponsors lose patience and scope gets cut from the end of the plan. The parts that get cut are usually testing, redirect verification and analytics parity, which are the parts that determine whether the launch is survivable.
The sunk cost problem
A monolithic replatform is close to impossible to abandon halfway. Twelve months in, with no shipped pages, the only options are to finish or to write off the entire investment. That dynamic pushes teams to launch before they are ready and to defend the architecture afterward regardless of what the numbers say.
Phased work changes that. After phase one you have a shipped artifact, a measured result on real traffic and a credible option to stop. Before committing either way, it is worth revisiting when headless commerce actually pays for a retailer, because the honest answer depends on catalog size, content velocity and whether your team can staff a front end permanently rather than on the appeal of the architecture.
What the risk actually looks like
| Dimension | Big bang cutover | Phased (strangler) |
|---|---|---|
| Revenue exposed per release | 100% of sessions | Share of traffic on migrated routes |
| Time to first measurable result | End of project, often 9–18 months | First phase, typically 6–12 weeks |
| Rollback mechanism | DNS and cache revert, hours to days | Routing rule flip, seconds to minutes |
| Attribution of a conversion drop | Dozens of simultaneous changes | One page type, one variable |
| Ability to stop the programme | Effectively none mid-project | Explicit decision point per phase |
| Peak infrastructure cost | Short overlap at the end | Two front ends running for months |
| Team cognitive load | One very large release | Sustained dual-stack maintenance |
The phased column is not free. Running two front ends means two deployment pipelines, two sets of dependencies to patch and a routing layer that becomes critical infrastructure. That is the trade: you pay a continuous operational tax in exchange for removing the single catastrophic release.
What the strangler pattern actually means for a storefront
The pattern comes from microservices practice, where a legacy application gets surrounded by a facade and functionality is peeled off piece by piece until the original is no longer called. The original is never rewritten in place. It is slowly left with nothing to do, and then switched off.
Applied to a storefront, the facade is a routing layer at the edge. Every request hits that layer first. If the request path matches a rule for a migrated page type, the layer proxies to the new front end. If it does not, the request falls through to the legacy platform exactly as before. Shoppers see one domain, one session and one cart.
If the vocabulary here is still fuzzy, it is worth reading headless commerce explained without the marketing buzzwords first, because the phased approach only makes sense once you can separate the presentation layer from the commerce engine in your own mental model of the stack. The migration is a front-end programme. The commerce APIs underneath usually stay where they are.
The three components you have to own
A workable hybrid has three moving parts. The first is the edge router, which owns path matching and the fallback rule. The second is a shared session and cart contract, so a shopper who browses a migrated category page and then lands on a legacy product page keeps the same basket. The third is a design token layer, so both front ends render the same brand without manual CSS drift.
Most teams underestimate the second. Cart continuity across two front ends usually means the cart lives in the commerce API or in a first-party cookie both applications can read, not in framework-specific state. Getting this wrong produces the single worst hybrid bug: a shopper adds to cart on one page type and the basket appears empty on the next.
Where the commerce engine sits
The phased pattern works best when the backend stays constant through the whole programme. If you are also swapping the commerce platform, you have two migrations stacked on each other and the routing layer no longer isolates anything useful. Teams that need both usually do the backend move first with the legacy front end intact, then start the front-end phases. The shortlisting work in the 2026 headless commerce stack worth shortlisting is the right input for choosing the front-end framework and the rendering host, which are the two decisions you cannot easily reverse later.
Choosing the first page type to move
The first phase should maximise learning and minimise damage. That rules out checkout, account pages and anything that handles payment data. It also rules out the page type that carries the most organic traffic, because a ranking mistake there is expensive and slow to detect.
The usual answer is editorial content, buying guides, or category and collection listing pages. Content pages are the softest landing: they are often the least coupled to commerce state, they are easy to render statically, and a rendering regression costs you engagement rather than orders. Category pages are the more useful lesson, because they exercise faceted navigation, pagination, sorting and product data, which is most of what the new stack will have to do well.
Ranking the candidates
| Page type | Transactional risk | Organic exposure | Build complexity | Good first phase? |
|---|---|---|---|---|
| Editorial and blog content | Very low | Moderate | Low | Yes, as a warm-up |
| Category and collection listings | Low | High | Medium to high | Yes, the standard choice |
| Product detail pages | Medium | Very high | High | Phase two or three |
| Search results | Medium | Usually blocked from index | Medium | Good if search is already a weak point |
| Cart | High | None | Medium | Late phase only |
| Checkout | Very high | None | High, plus compliance scope | Last, or never |
| Account and order history | Medium | None | Medium | Low priority, little upside |
One useful filter: pick a page type where you already know the current numbers cold. If you cannot state the current conversion rate, bounce rate and median largest contentful paint for a page type from memory or from a saved report, you will not be able to tell whether the migration helped. Measurement readiness is a selection criterion, not a follow-up task.
Scoping the slice narrowly
Even inside one page type, you can go narrower. Moving one category tree, or the categories in a single market, gives you a real production test on a fraction of sessions. Teams that run multiple storefronts often migrate the smallest country site first for exactly this reason, then reuse the components on the larger markets once the pattern is proven.
The counterargument is fragmentation. Every additional slice boundary is another set of rules in the router and another chance for an inconsistency to leak into the shopper experience. Two or three phases that each move something substantial beats a dozen micro-phases that leave the site permanently half-built.
Routing traffic between old and new front ends
The router is where a phased migration lives or dies. It needs to decide, per request, which front end serves the response, and it needs to do that without adding meaningful latency or breaking caching. There are four common implementations, and the differences matter more than vendors usually admit.
Comparing the routing approaches
| Approach | How it works | Strength | Main drawback |
|---|---|---|---|
| CDN or edge path rules | Rules at the CDN map URL patterns to one of two origins | No change to application code, instant flip, easy rollback | Rule sprawl; cache keys and headers need careful design |
| Reverse proxy you operate | Your own proxy tier in front of both origins | Full control over rewriting, headers and gradual percentage rollout | You now run and scale a critical hop yourself |
| New front end as the default origin | New stack receives everything and proxies unmigrated paths back to legacy | Single origin to reason about, simple for the CDN | Legacy outages now look like new-stack outages; blast radius grows |
| Subdomain or path prefix split | Migrated pages live on a visibly different host or prefix | Trivial to implement, no shared routing logic | Changes URLs, which is the one thing you most want to avoid |
The subdomain option is listed because teams keep reaching for it and it is almost always the wrong call for pages that rank. Moving a page type to a new host means a redirect for every URL, a new set of signals to consolidate and a cookie scope question for session continuity. If the page type has no organic value, a prefix split is defensible. For categories and products, it is not.
Percentage rollouts and the control group
Edge routing lets you send a share of sessions to the new front end for the same URL. That is the most valuable capability in the whole programme, because it turns the migration into a measurable experiment rather than a before-and-after story. Ten percent for a week, then fifty, then full, with conversion and performance tracked per arm.
Two cautions. Serving different HTML to different users at the same URL needs a consistent assignment, usually a hashed cookie, so a shopper does not flip between front ends mid-journey. And the variant you serve to crawlers should be one version, held stable for the duration, rather than a coin flip on every fetch.
Caching with two origins
Both front ends will want different cache behaviour. The legacy platform probably relies on full-page cache with cookie-based bypass rules; a modern front end may use incremental static regeneration or stale-while-revalidate semantics. Running both behind one CDN configuration means the cache key definition has to be explicit per route group rather than global.
The failure to watch for is a migrated route inheriting a legacy bypass rule, which quietly turns every request into an origin hit. That shows up as a cost spike and a latency regression that looks like the new framework underperforming when it is really a cache miss problem.
Keeping URLs, redirects and canonicals stable
The single rule that saves the most traffic is also the simplest: a migrated page keeps the exact URL it had before. Same path, same casing, same trailing slash behaviour, same pagination parameters. If the new framework prefers a different convention, the framework loses that argument.
This sounds obvious and gets violated constantly, because modern routers have opinions. Some normalise trailing slashes, some lowercase paths, some want pagination as a path segment rather than a query parameter. Each of those turns a stable URL into a redirect, and a site mid-migration can end up with half its URLs one hop longer than they were.
The checks that belong in your release gate
- Byte-for-byte URL parity: export every URL of the page type from logs or the sitemap, request each through the router, and assert a 200 with no redirect.
- Self-referencing canonicals: the new front end must emit the absolute canonical for the live URL, not a localhost or preview-domain variant, which is the most common staging leak.
- Trailing slash consistency: whichever form the legacy site served, the new one serves the same, and the other form 301s to it.
- Pagination and facets: indexable parameter combinations stay indexable and non-indexable ones keep their robots directives.
- Redirect chains: no migrated URL may sit behind more than one hop; audit the full chain, not just the final status code.
- Sitemap sourcing: decide which front end owns the sitemap during the overlap, and make sure it lists URLs from both.
Rendering is the other half. A client-rendered page that serves an empty shell to the first request can be indexed eventually, but the latency between publish and indexation gets longer and the behaviour becomes harder to predict. The rendering and routing specifics are covered in more depth in headless commerce SEO: rendering, routing and the mistakes that cost traffic, and the short version is that server rendering or static generation for anything you want ranked is not a performance preference, it is a requirement.
Structured data and head tags
Head tag parity deserves its own checklist because it is invisible in a visual QA pass. Titles, meta descriptions, Open Graph tags, hreflang clusters and product or breadcrumb structured data all need to match or improve on the legacy output. The fastest way to verify is a diff: fetch the legacy HTML and the new HTML for the same URL, extract the head, and compare field by field.
Hreflang is the one that breaks most often in a partial migration, because the cluster has to reference URLs on both front ends. If the migrated English page lists hreflang alternates that only exist in the new stack, the unmigrated language versions drop out of the cluster and the whole set degrades.
Analytics and tag parity during the overlap
A migration you cannot measure is a migration you cannot defend. During the overlap, the same shopper journey can cross both front ends, and if the two stacks instrument events differently, your funnel reports will show a drop that is pure measurement artifact.
Start by freezing the event schema before any code is written. Event names, parameter names, currency handling and item identifiers must be identical in both implementations. The new front end should not take the opportunity to modernise the tracking plan at the same time. Change one thing.
The parity checklist
- Session continuity: the client ID must survive a cross-front-end navigation, which means cookie domain and path scoped to the apex, not to a prefix.
- Consent state: the consent decision has to be readable by both stacks; a consent banner that reappears when a shopper crosses the seam is both a compliance problem and a visible defect.
- Event deduplication: if both the legacy template and the new front end fire a view event during a transition, your counts inflate and conversion rate deflates.
- Server-side tagging: if you run a server container, both front ends point at the same endpoint with the same payload shape.
- Attribution parameters: campaign parameters must survive the proxy hop; strip them at the edge and paid reporting collapses.
- Performance monitoring: real user monitoring needs a route-group dimension so you can compare migrated routes against the rest of the site rather than against a site average.
Build a side-by-side dashboard before the first phase launches, not after. It should show the migrated route group and a comparable unmigrated group on the same axes: sessions, conversion rate, revenue per session, core web vitals and error rate. Without the control group, every seasonal swing becomes an argument about the architecture.
Watch the lagging indicators
Conversion and performance move within days. Organic traffic, indexation and crawl behaviour move over weeks, and they are the metrics most likely to reveal a mistake that did not show up in QA. A phase is not validated at launch plus one week. Hold the judgement until you have seen a full crawl cycle for the migrated page type, which on most mid-sized retail sites means at least a month.
Checkout: the last thing you should touch
Checkout is the page type with the worst risk-to-reward ratio in the entire migration. It carries no organic value, it holds the highest conversion stakes, and on most platforms it drags payment compliance scope along with it. Rebuilding it buys you design freedom on a flow where design freedom is rarely the constraint.
The common sequence is therefore: content, categories, product pages, cart, and then a deliberate pause. Plenty of retailers run a headless front end for discovery and keep the platform-native checkout indefinitely, handing off at the cart boundary. That hybrid is a legitimate end state, not an unfinished project.
If you do migrate it
Treat it as its own programme with its own gate. That means a percentage rollout measured in single digits at the start, a hard rollback path that does not require a deploy, and a fraud and payments review before any real card data flows. Promotion and tax logic should stay in the commerce engine rather than being reimplemented in the front end, because a discount that calculates differently in two places is a reconciliation problem you will be unpicking for quarters.
The honest test is whether you can name the specific revenue mechanism the new checkout unlocks. One-page flows, wallet buttons placed higher, or a working express path are real mechanisms. Framework consistency is not. If the only answer is that the old checkout feels dated, the budget is better spent on product pages.
Deciding to stop or continue after phase one
Write the decision criteria before the phase starts and store them where the sponsor can see them. After the fact, every result can be argued into a mandate to continue, which defeats the main advantage of phasing in the first place.
Useful criteria are concrete and pre-committed: conversion rate on the migrated route group within a stated tolerance of control, no sustained organic decline attributable to the page type, time-to-publish for a new landing page cut by a named factor, and delivery velocity after launch measured in shipped changes per sprint rather than in developer sentiment.
Three honest outcomes
| Outcome | What the data looks like | Reasonable next step |
|---|---|---|
| Continue | Conversion flat or better, performance improved, team shipping faster | Start phase two on product pages with the same gate |
| Pause and consolidate | Metrics flat, but delivery is slower and the team is stretched | Hold the hybrid, fix tooling and staffing, revisit in a quarter |
| Stop | No measurable gain, two stacks costing more than one delivered | Keep the migrated slice or route it back, and close the programme |
Stopping is the outcome teams are least prepared to execute, which is odd given that the routing layer makes it cheap. If the new front end did not earn its keep on the first page type, flipping the rule back is a configuration change, and the work is not wasted: you bought a real answer for the price of one phase instead of twelve months.
Budgeting the overlap
The one cost that consistently surprises finance is the duration of the dual-stack period. Two sets of hosting, two monitoring footprints, two dependency upgrade treadmills and a routing tier that needs on-call coverage. If phase two slips, that overlap stretches, and the saving you modelled against the legacy licence never arrives.
That is also why the decision belongs next to the platform question rather than inside the engineering backlog. The framing in how to choose the right e-commerce platform for your store applies directly here: the right answer depends on catalog complexity, content cadence and the engineering capacity you can commit for years, not on which architecture reads better in a vendor deck. A phased migration does not change that calculus. It just lets you buy evidence in instalments.
What a reasonable timeline looks like
For a mid-sized retailer with a single market and a catalog in the low tens of thousands of SKUs, a realistic shape is 6–10 weeks to the first content or category phase, including the routing layer, and a 4–6 week measurement hold before the decision. Product pages are typically a longer phase because of variant logic, reviews, inventory signals and structured data.
Multi-market retailers should add time rather than parallelising. Localisation, tax display, hreflang clusters and market-specific payment badges each multiply the test matrix, and the point of the phased approach is to keep the number of simultaneous variables small.
Common mistakes worth naming
Most phased migrations that go badly share a small set of errors, and all of them are avoidable at planning time rather than in the middle of a release.
- Changing URLs because the new router prefers it. The framework is the junior party in that negotiation.
- Rebuilding the tracking plan at the same time. You lose the ability to compare before and after, which is the whole point of phasing.
- Letting the design drift. Two front ends with slightly different type scales and button styles read as a broken site to shoppers even when nothing is technically wrong.
- Skipping the control group. Without an unmigrated comparison group, seasonality will be mistaken for impact in both directions.
- No written stop criteria. Phasing without a gate is a big bang delivered in slices.
- Treating the router as a side project. It becomes the most critical hop on the site and needs ownership, monitoring and runbooks.
- Starting with checkout because it is the most visible. Visibility and risk are not the same axis.
For context on how large the stakes are, the US Census Bureau’s quarterly retail e-commerce report is the standard public reference for what share of retail sales now moves online; check the current release for the latest figures, as they are revised. The relevant point for this discussion is simply that for most retailers the front end is now a primary sales channel, which is the reason you do not want to replace all of it on a Tuesday night.
FAQ on phased headless migrations
How long can two front ends safely run side by side?
Indefinitely, from a technical standpoint, provided the routing rules, session contract and design tokens are properly owned. The real limit is organisational: the overlap costs money and attention every month, so most teams set a target of two to four phases over 9–18 months, with an explicit decision to either finish or formalise the hybrid as a permanent architecture.
Will a phased migration hurt SEO?
It should not, and it is usually safer than a full cutover, because fewer URLs change behaviour at once. The risk comes from URL drift, missing or wrong canonicals, client-only rendering and broken hreflang clusters, all of which are preventable with a release gate that checks URL parity and head tag parity before each phase goes live.
Should migrated pages live on a subdomain?
Avoid it for any page type with organic value. A subdomain forces a redirect for every URL, splits cookie scope and adds signal consolidation work you would not otherwise need. Use edge path routing on the same host so the URL a shopper or crawler requests stays exactly the same.
What is the smallest viable first phase?
A single page type with low transactional risk and known baseline metrics. Editorial content is the softest option; one category tree is the more informative one, because it exercises faceting, pagination and product data. Avoid phases so small that they teach you nothing about the stack under real conditions.
Can the cart stay on the legacy platform?
Yes, and for many retailers it should. Handing off at the cart or checkout boundary is a common and durable arrangement. It requires that cart state lives in the commerce API or in a cookie both front ends can read, so the basket survives the transition between page types.
How do we compare the new front end fairly against the old one?
Use a percentage rollout at the edge with consistent user assignment, and keep an unmigrated route group as a control. Compare sessions, conversion rate, revenue per session, core web vitals and error rate on the same chart. Serve crawlers one stable variant rather than splitting them across arms.
Does a phased approach cost more in total?
Usually yes in direct spend, because of the dual-stack overlap, and usually less in risk-adjusted terms, because you can stop after any phase. The comparison that matters is not total project cost but the cost of discovering that the architecture does not fit, which a big bang only reveals after the whole budget is committed.
What if phase one shows no improvement at all?
That is a result, not a failure. Flat conversion with no delivery speed gain is the signal to pause or stop, and the routing layer makes reverting cheap. Many retailers in that position keep the migrated slice, cancel the remaining phases and redirect the budget to merchandising or performance work on the existing stack.
Who should own the routing layer?
Whichever team is on call for the storefront, with documented runbooks and alerting. It is not a project artifact that can be handed to an agency and forgotten, because once it is live every request on the site passes through it and a misconfigured rule can take down page types that were never part of the migration.